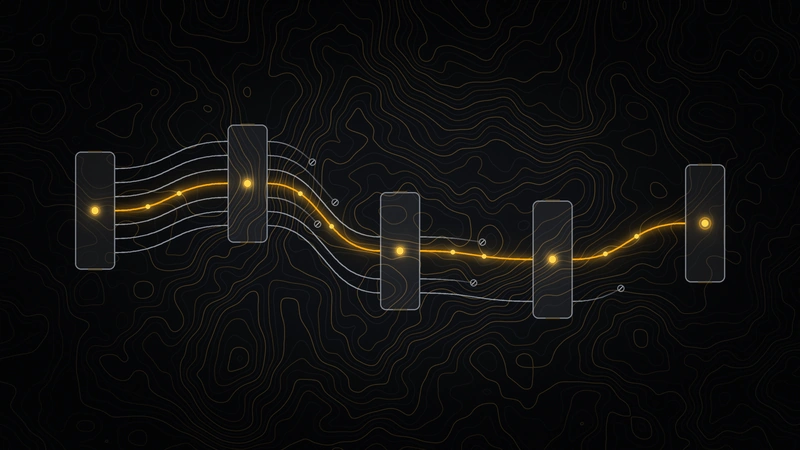
Five quick repairs went out in one day. If they had shipped as a single package, one bad repair would have forced a choice between pulling back four working fixes or hunting through a pile of changes while the live app had a problem. So we split them into six numbered releases, each holding one ticket or one pair that belonged together. Release number three could turn out wrong, and the two repairs before it would stay live.
What went out that day
Earlier that morning we had made the normal small release. Then came five quick repairs for things already in use. People call that a hotfix, which just means a small repair sent out quickly instead of waiting for the next regular update.
The first idea we had to rule out was putting all five repairs in one big package. If one repair in that package caused trouble, we would have two bad choices. We could pull the whole package back and remove four repairs that were helping. Or we could hunt through a pile of changes, trying to remove only the bad one while the live app was having a problem. Either choice costs time and patience at exactly the wrong moment.
So we kept the boxes small. Each quick repair was tied to one ticket, which is simply the written note describing one piece of work. Four releases each held one ticket. One held a pair that belonged together. The number six did not matter. What mattered was that we could say what was inside every numbered release without opening a long list of code changes.
Think about leftovers in a refrigerator. If every meal is shoved into one large container, you cannot throw out the spoiled part without losing everything else. If the meals are in separate containers, the bad one can go and dinner is still there. The numbered releases worked the same way. If the third repair turned out to be wrong, the answer was simple: return to the numbered release just before it. That leaves the earlier repairs in place and removes only the change that needs attention.
We did not add an extra approval line or a long waiting period between making a repair and sending it out. What we had was a clear place to stand if we needed to step back. A release number was the label on a small, known box.
Keeping the live app and the next release in agreement
There was another part that could have made the day harder. A quick repair starts from the live version of the app, because that is the version people are using. After it goes out, the same repair also has to be copied into the ongoing work for the next normal release. If we skipped that second step, the live app and the next release would slowly become different stories. A repair already sent out could disappear later, or the next release could turn into an argument over which version number was right.
Technical people call the separate work copies used for this a branch. It is like taking one sheet from a recipe binder to make a specific correction on it, while leaving the rest of the binder alone. We kept each repair on its own separate copy until it was ready. That kept one small change from being mixed with another before either had been checked.
How we checked, and where the check stops
None of this meant a repair was sent out blind. Before a release, we ran it on a local copy of the app that matched the live one as closely as practical. We clicked the thing that had changed and watched it do the right thing.
That check has a limit. A repair that changes a screen or fixes a query can often be seen with your own eyes. A change that depends on something you cannot see locally, such as a job that runs later or behavior that appears only under real traffic, is different. We would not use this fast path for that kind of work. A quick return point helps, but it does not replace a proper chance to watch a hard-to-see change behave in the real world.
The work that stayed out of the line
The same day included work that did not belong in the quick-repair line at all. A new analytics area, several thousand lines spread across new pages, went into the next regular release instead. It was new work, not a repair to something people already depended on, so it had no “last good box” to return to. Size was not the test. The question was whether the change touched live behavior that needed a clean, independent way back.
What to ask your team or vendor
Ask whether each production fix ships as its own numbered release that can be undone alone. Check that every repair sent out against the live app is also carried into the next regular release. Reserve this fast path for changes you can see working on a local copy, and give changes that only show up later or under real traffic a proper chance to be watched.